Research1 мин
Hugging Face Journal Club: Score Centering Stabilizes Off-policy Reinforcement Learning
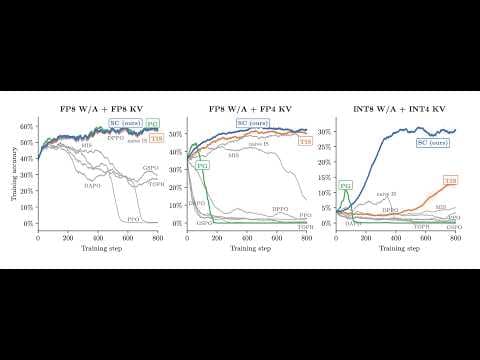
Yeah, the gist of the paper as you uh probably saw is just uh to identify the fundamental reason why RL learning for LLMs becomes unstable when there's a mismatch between the the inference engine and the training engine and uh the authors kind of uh go through the the math of…
YouTube — Hugging Face