PAIR: Bridging Perception and Action in Vision-Language-Action Models
Vision-language-action (VLA) models map visual observations and language instructions to continuous robot actions. This task requires a transition from representations that describe the scene and instruction to representations that support action generation. Many…
AI Summary & Key Takeaways
- Vision-language-action (VLA) models map visual observations and language instructions to continuous robot actions
- This task requires a transition from representations that describe the scene and instruction to representations that support action generation
PAIR: Bridging Perception and Action in Vision-Language-Action Models
Related stories
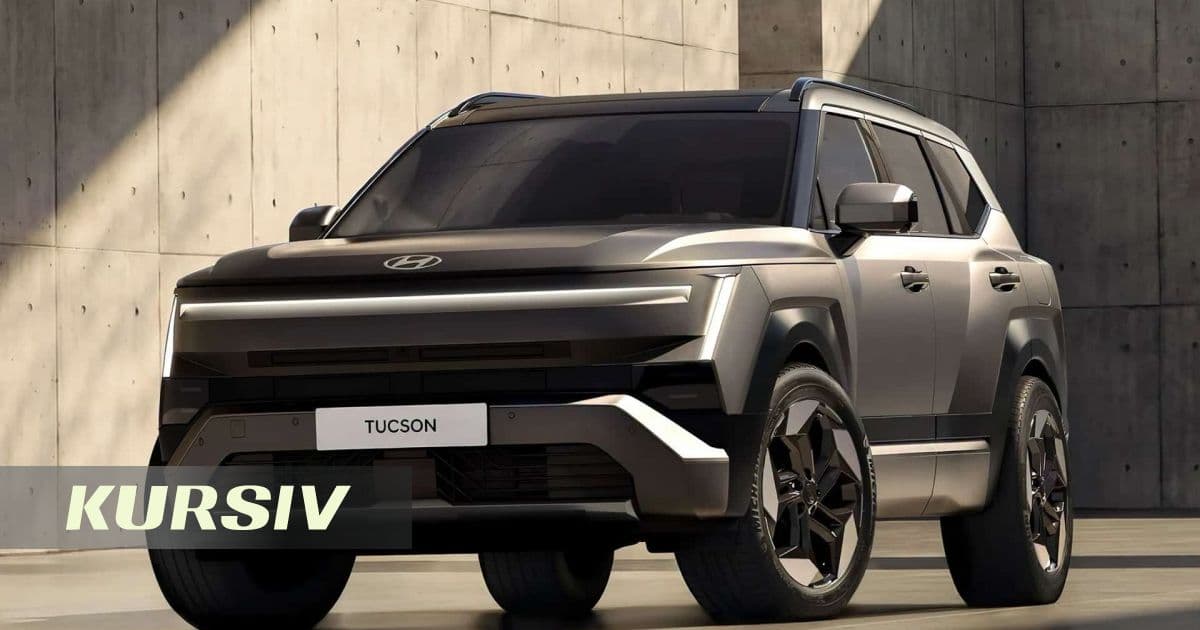
The new Hyundai Tucson collected 15 thousand orders in the first day
Hyundai has started taking orders for the fifth-generation Tucson in South Korea and received 15,045 orders on the first day. This is noticeably more than the predecessor collected when entering the market in September 2020. Then the model received 10,842 orders. The hybrid outperformed the gasoline version...
Ensemble forecasting with IBM Granite time-series models
A Blog post by IBM Research on Hugging Face

A Chinese company has shown a bodyguard robot that can master kung fu.
The Chinese company Unitree Robotics introduced the humanoid robot H2-X, which can perform acrobatic stunts, fight off attackers and participate in saving people. In the demo video, the robot jumps from a height, does somersaults and even lifts a car.…
Jensen Huang brought mini-robots to the stage and talked about the future of AI
🤖 Jensen Huang brought mini-robots to the stage and spoke about the future of AI While we are waiting for the head of NVIDIA in Kazakhstan, he spoke at the NVIDIA GTC Berlin 2026 conference and demonstrated the MicroDuck robots created by the French Pollen Robotics. Little robots were trained to walk...