MoRI + vLLM: Wide Expert Parallelism and RDMA KV-Cache Transfer for Disaggregated MoE Serving on AMD
Running large Mixture-of-Experts models across pods creates two major challenges: expert dispatch and combine traffic, and moving the KV cache between prefill and decode. At North America 2026, Ravi Gupta, Rishi Madduri, and Shiksha Patel of AMD will present “MoRI + vLLM: Wide…
AI Summary & Key Takeaways
- Running large Mixture-of-Experts models across pods creates two major challenges: expert dispatch and combine traffic, and moving the KV cache between prefill and decode
- At North America 2026, Ravi Gupta, Rishi Madduri, and Shiksha Patel of AMD will present “MoRI + vLLM: Wide…
Related stories
Jensen Huang brought mini-robots to the stage and talked about the future of AI
🤖 Jensen Huang brought mini-robots to the stage and spoke about the future of AI While we are waiting for the head of NVIDIA in Kazakhstan, he spoke at the NVIDIA GTC Berlin 2026 conference and demonstrated the MicroDuck robots created by the French Pollen Robotics. Little robots were trained to walk...
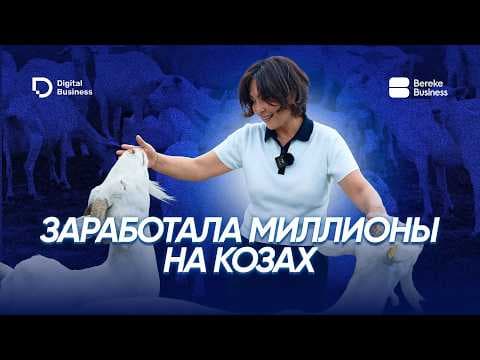
Swapped a corporate career for a goat farm and earns $800,000 a year
They snorted and grumbled, they didn't like something. It turns out fruits and berries were much harder than goats. I am Zhuldys Kozhakhanova. Welcome to the Golomelk goat farm. I am a pediatrician, but I worked in the pharmaceutical industry for a long time. And once I had…
RUОткрытые модели NVIDIA поддерживают проекты в европейском госсекторе
Новые открытые модели NVIDIA помогают европейским правительствам эффективно управлять данными.
RUЕвропейские пионеры используют модели NVIDIA Earth-2 для прогноза погоды
Модели NVIDIA Earth-2 помогают прогнозировать погоду и климат в Европе.