Byte Latent Transformer: Patches Scale Better Than Tokens (Paper Explained)
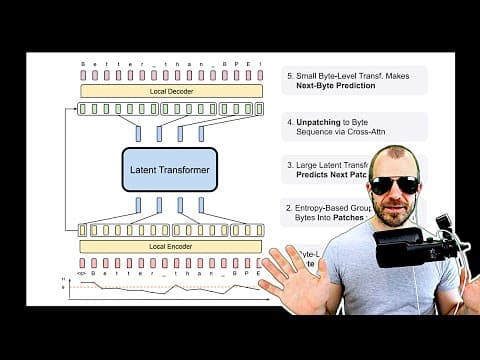
hello there today we're looking at the paper bite lat and Transformer patches scale better than tokens this paper in a sense does away with classic fixed vocabulary based tokenization and in doing so develops a new architecture called The Bite latent Transformer and in their…

![[GRPO Explained] DeepSeekMath: Pushing the Limits of Mathematical Reasoning in Open Language Models](/_next/image?url=https%3A%2F%2Fi.ytimg.com%2Fvi%2FbAWV_yrqx4w%2Fhqdefault.jpg&w=3840&q=75)


![[Paper Analysis] The Free Transformer (and some Variational Autoencoder stuff)](/_next/image?url=https%3A%2F%2Fi.ytimg.com%2Fvi%2FNao16-6l6dQ%2Fhqdefault.jpg&w=3840&q=75)
![[Video Response] What Cloudflare's code mode misses about MCP and tool calling](/_next/image?url=https%3A%2F%2Fi.ytimg.com%2Fvi%2F0bpYCxv2qhw%2Fhqdefault.jpg&w=3840&q=75)
![[Paper Analysis] On the Theoretical Limitations of Embedding-Based Retrieval (Warning: Rant)](/_next/image?url=https%3A%2F%2Fi.ytimg.com%2Fvi%2FzKohTkN0Fyk%2Fhqdefault.jpg&w=3840&q=75)